How to Make the Virgínia and the Boy AI Trend
Make the same parking-lot serenade with yourself as the singer. Solo replaces the boy on the left; duo replaces both people using two separate photos. The reference voice stays in Brazilian Portuguese. Your photo changes who appears, without cloning your singing voice.
Standard or Premium
| Edition | Duration | Credits |
|---|---|---|
| Standard · Seedance 2.0 Mini | 10s | 480p: 100 · 720p: 140 |
| Premium · Kling 4.0 | 25s | 720p: 300 · 1080p: 500 |
Both editions use the same generator and support solo or duo. Standard uses a later excerpt with a short audio tail after the final phrase; Premium keeps the full scene.
The original and the AI remakes
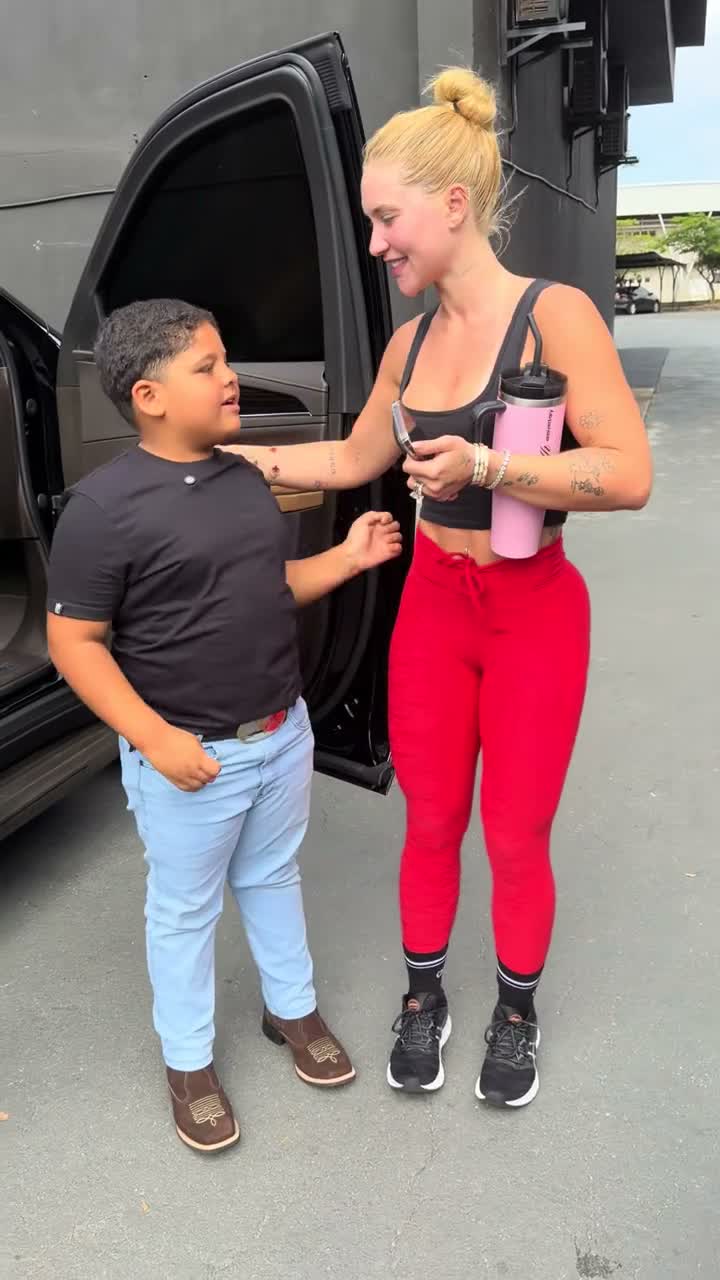
The original shows Tim Vaqueiro singing to Virginia beside an open SUV door. R7 documented AI remakes on 12 November 2026, including versions recasting both roles. The comparison below contains the original and a credited external AI remake, not a verified output from this tool.
Make the solo or duo version
Choose a cast
Solo replaces the singer; duo replaces singer and listener.
Upload photos
Use a sharp photo with an unobstructed face for each selected role.
Generate
Choose Standard (10s, 480p 100 / 720p 140 credits) or Premium (25s, 720p 300 / 1080p 500 credits).
Download
Review faces and lip-sync, download the MP4 and label the remake as AI-generated when sharing.
Make the Virgínia & the Boy video with 2 photos
25-second 9:16 video with the trend sound, from 100 credits. No prompt needed.
Open the Virgínia & the Boy generatorChoose photos for the two roles
| Mode | Uploads | Replacement |
|---|---|---|
| Just me singing | 1 photo | Left singer only; Virginia stays |
| Two people | 2 separate photos | Image 1: singer; image 2: listener |
Use a sharp adult portrait with the mouth and hair visible. The singer faces the listener in three-quarter profile. Each uploaded person keeps their own outfit and adult proportions. Duo requires both photos; a photo for only the listener is not a supported mode.
A prompt you can adapt
Solo prompt: Recreate the vertical parking-lot serenade using @video_1 as the full silent video for camera movement, gestures and mouth shapes. Replace only the left singer with the adult in @image_1, preserving their face, hair, adult proportions and outfit. Preserve the original listener on the right: blonde bun, black sports top, red leggings, pink tumbler and phone. The singer performs earnestly with hands clasped while she laughs, covers her mouth and touches their shoulder. No audio, added text or extra foreground people.
For duo, use the AI motion reference and replace the instruction about the original listener with: The right listener is the adult in @image_2; preserve their face, hair, build and outfit. Never swap identities or positions. Use the full 25-second motion clip as @video_1 and generate once with Kling 4.0, preserving the same cast, lighting and clothes. Reference the singer as @image_1 and the listener as @image_2.
Add the matching Portuguese soundtrack
Generate the full 25 seconds with the silent reference, then lay the matching source audio over the result starting at zero. Any model-generated audio is replaced by that track, or removed when soundtrack is off. Solo and duo use separate aligned tracks. Do not slow down only the picture or mix the original audio with the AI remake's motion. Turn soundtrack off for a silent export. This template does not accept voice recordings or clone voices.
Review the result
- Check face, clothing and body continuity throughout the 25-second shot.
- Keep the singer on the left and listener on the right.
- Inspect hands around the mouth, shoulder, phone and tumbler.
- Check that audio stays aligned without a repeat or offset.
- Lip-sync follows the reference motion; exact phoneme timing is not guaranteed.
Kling 4.0 generates all 25 seconds in one task. Review faces and lip-sync before sharing.
FAQ
Can I replace only the boy?
Yes. Choose Just me singing and upload one clear adult portrait. Only the left singer is recast; Virginia stays in the scene.
How do I replace both people?
Choose Replace both people and upload a separate photo for each role. Singer is image 1; listener is image 2. Both photos are required.
Will I hear my own singing voice?
No. The video uses the matching Portuguese reference audio. There is no voice upload or voice cloning in this template.
What is the song?
The reference features Aproveita Que Eu Tô Brigado, associated with NATTAN and Zé Vaqueiro. The clip's voice and ambient sound are composited after generation.
Are the previews made on this site?
No. The original and the credited AI remake are external references. They do not demonstrate a verified generation from this tool.